
Exam Overview
| Exam Code | AI-300 |
| Exam Name | Operationalizing Machine Learning and Generative AI Solutions (beta) |
| Vendor | Microsoft |
| Total Questions | 116 |
| Last Updated | 26-Oct, 2026 |
Why CertsPoint?
- Latest & Verified Questions
- Detailed Explanations
- Regular Updates
- Full-Length Practice Tests
- Boost Your Exam Confidence
PDF Study Materials
Downloadable guides and resources
Practice Tests
Full-length tests with real exam experience
Progress Tracking
Monitor your performance and improvement
Study Anywhere
Access on desktop, tablet, and mobile
Secure Payment
Privacy Protected
Money Back Guarantee
Free AI-300 Practice Questions
Explore 5 free practice questions for the Microsoft AI-300 exam and review the answers and explanations to support your preparation.
-
Question 1
Single answerYou manage an Azure Machine learning workspace. You develop a machine learning model. You must deploy the model to use a low-priority VM with a pricing discount. You need to deploy the model. Which compute target should you use?
-
Option A:Correct
Azure Container Instances (ACI)
-
Option B:Correct
Azure Machine Learning compute clusters
-
Option C:Correct
Local deployment
-
Option D:Correct
Azure Kubernetes Service (AKS)
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: B
Explanation
-
-
Question 2
Drag & DropA team trains an MLflow model that scores customer churn risk. The model will be consumed by different downstream systems. One system requests predictions synchronously during customer interactions. Another system submits files containing millions of records for scheduled scoring. You need to deploy the model by using managed inference options that match each usage pattern. Which option should you use for each usage pattern? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer
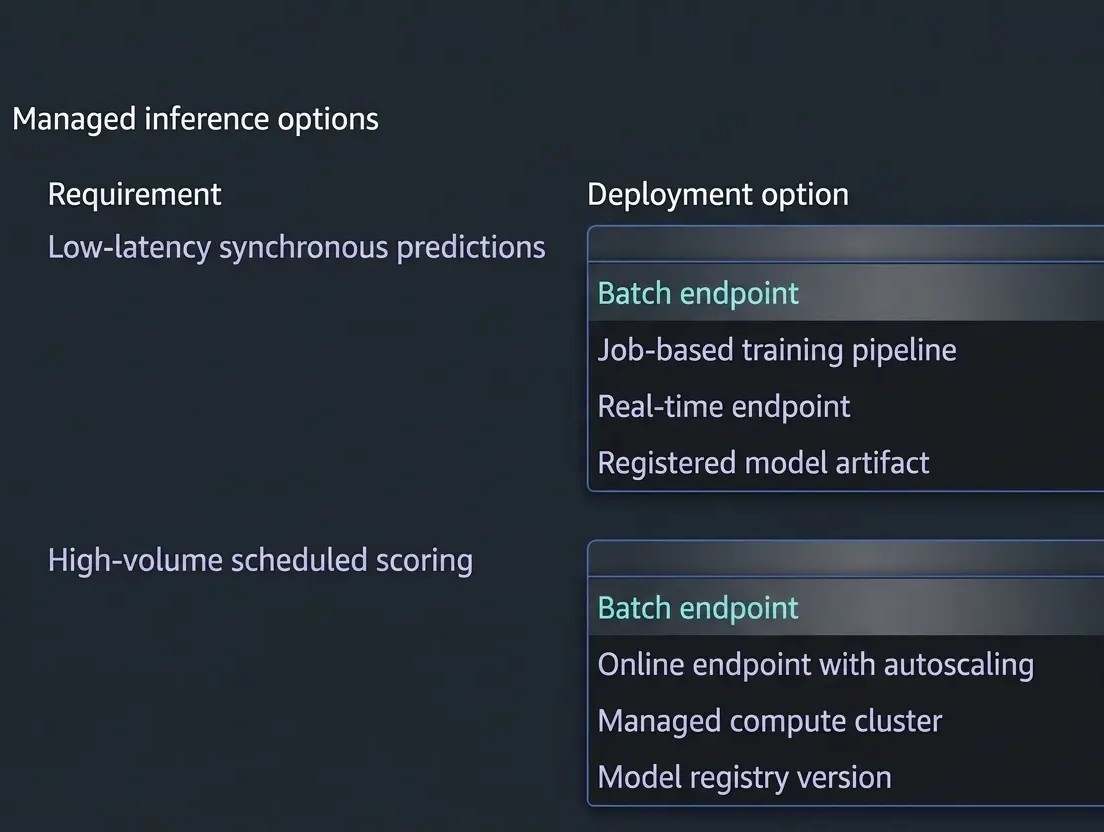
Explanation
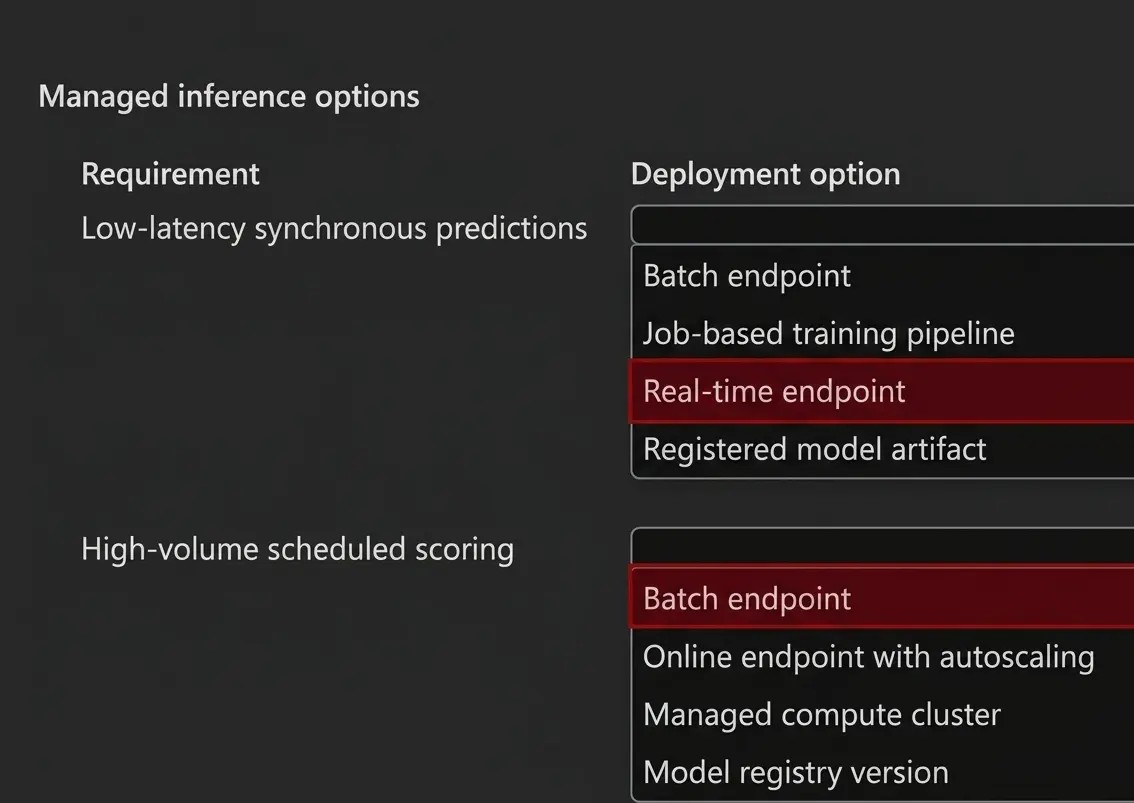
-
Question 3
Single answerYou need to recommend an experiment-tracking strategy that ensures consistent experiment results. What should you recommend?
-
Option A:Correct
Azure Machine Learning job output logs
-
Option B:Correct
MLflow experiment tracking
-
Option C:Correct
Application Insights logs
-
Option D:Correct
Azure Monitor alerts
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: B
Explanation
-
-
Question 4
Single answerYou need to isolate training workloads while remaining cost-aware to address Fabrikam Inc.’s issues, constraints, and technical requirements. What should you implement?
-
Option A:Correct
Training jobs that run on a single shared compute cluster
-
Option B:Correct
Fixed-size compute cluster
-
Option C:Correct
Dedicated compute clusters per experiment
-
Option D:Correct
Managed compute targets with autoscaling
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: D
Explanation
-
-
Question 5
Single answerYou need to standardize how Fabrikam Inc. manages machine learning assets. Which action should you perform first?
-
Option A:Correct
Register assets in the Azure Machine Learning registry
-
Option B:Correct
Create a shared Azure Machine Learning workspace.
-
Option C:Correct
Deploy a managed online endpoint.
-
Option D:Correct
Create a new Microsoft Foundry project.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: B
Explanation
A shared Azure Machine Learning workspace is the foundational step for standardizing how machine learning assets are managed across an organization. The workspace acts as a central environment where datasets, models, environments, pipelines, and compute resources are created, organized, and governed. By establishing a shared workspace first, Fabrikam Inc. ensures that all teams are working within a consistent structure, which enables proper collaboration, access control, and lifecycle management of ML assets.
Once the workspace is in place, other capabilities—such as registering assets in an Azure Machine Learning registry or deploying managed online endpoints—can be built on top of it. Without a standardized workspace, asset management would remain fragmented and inconsistent, making governance and reuse difficult. -