
| Exam Code | DP-800 |
| Exam Name | Developing AI-Enabled Database Solutions |
| Vendor | Microsoft |
| Total Questions | 61 |
| Last Updated | 26-Oct, 2026 |
- Latest & Verified Questions
- Detailed Explanations
- Regular Updates
- Full-Length Practice Tests
- Boost Your Exam Confidence
PDF Study Materials
Downloadable guides and resources
Practice Tests
Full-length tests with real exam experience
Progress Tracking
Monitor your performance and improvement
Study Anywhere
Access on desktop, tablet, and mobile
Free DP-800 Practice Questions
Explore 3 free practice questions for the Microsoft DP-800 exam and review the answers and explanations to support your preparation.
-
Question 1
Single answerYou have a Microsoft SQL Server 2025 instance that has a managed identity enabled.
You have a database that contains a table named dbo.ManualChunks. dbo.ManualChunks contains product manuals.
A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpoint for chat completions. The solution must provide the highest level of security.
You write the following Transact-SG1 code.
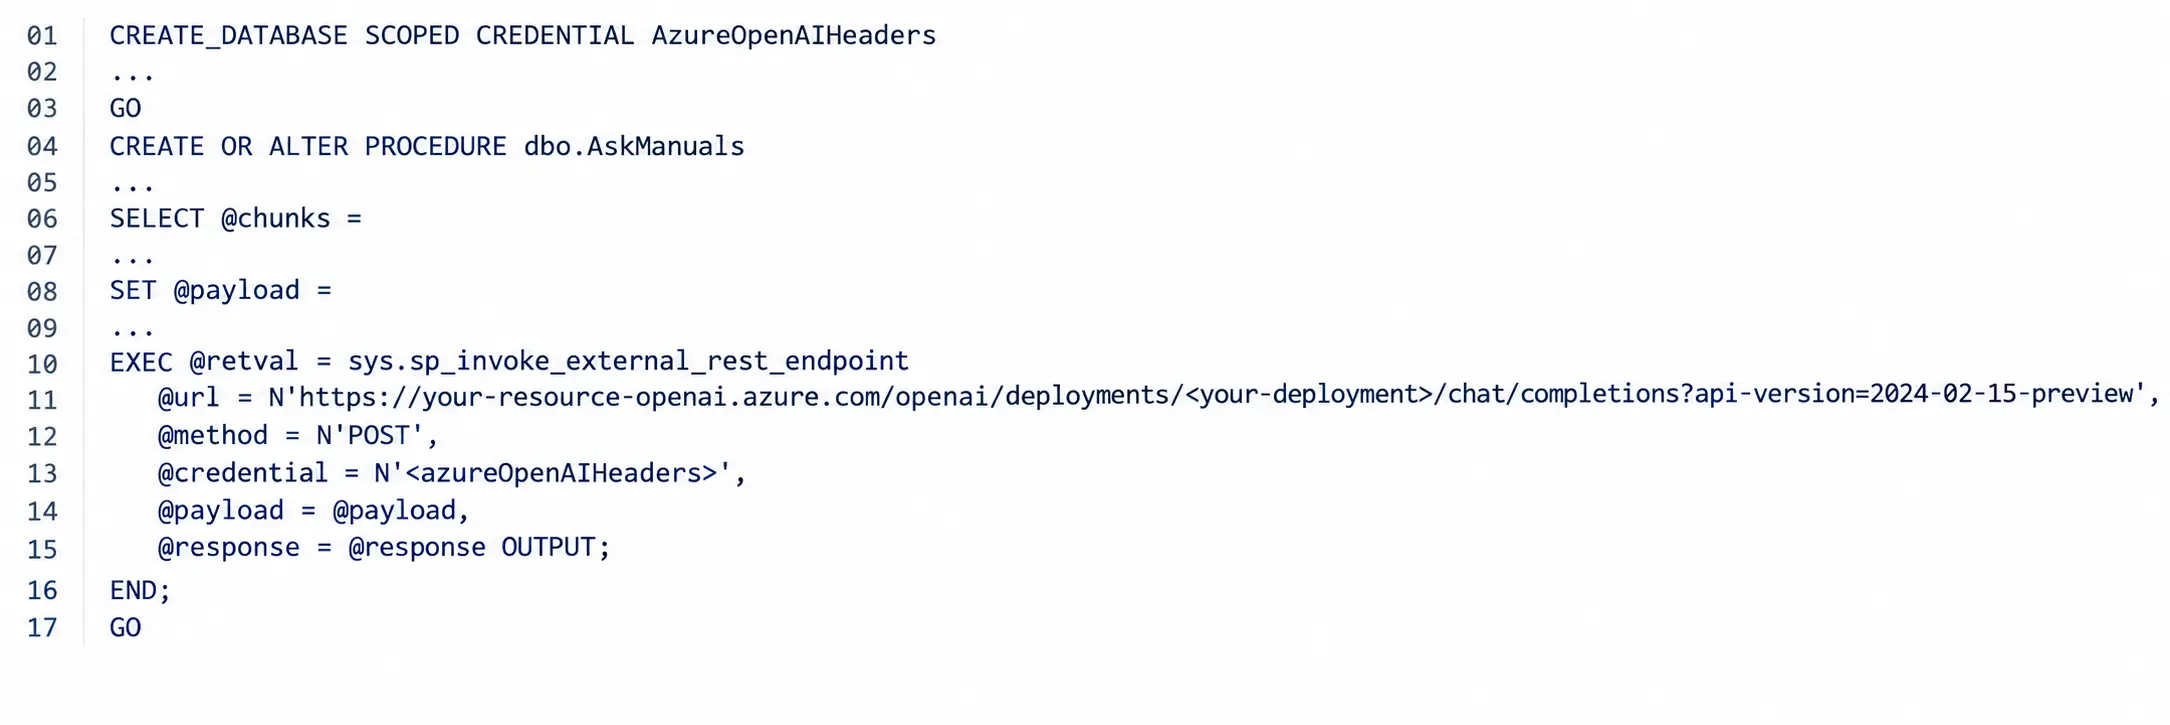
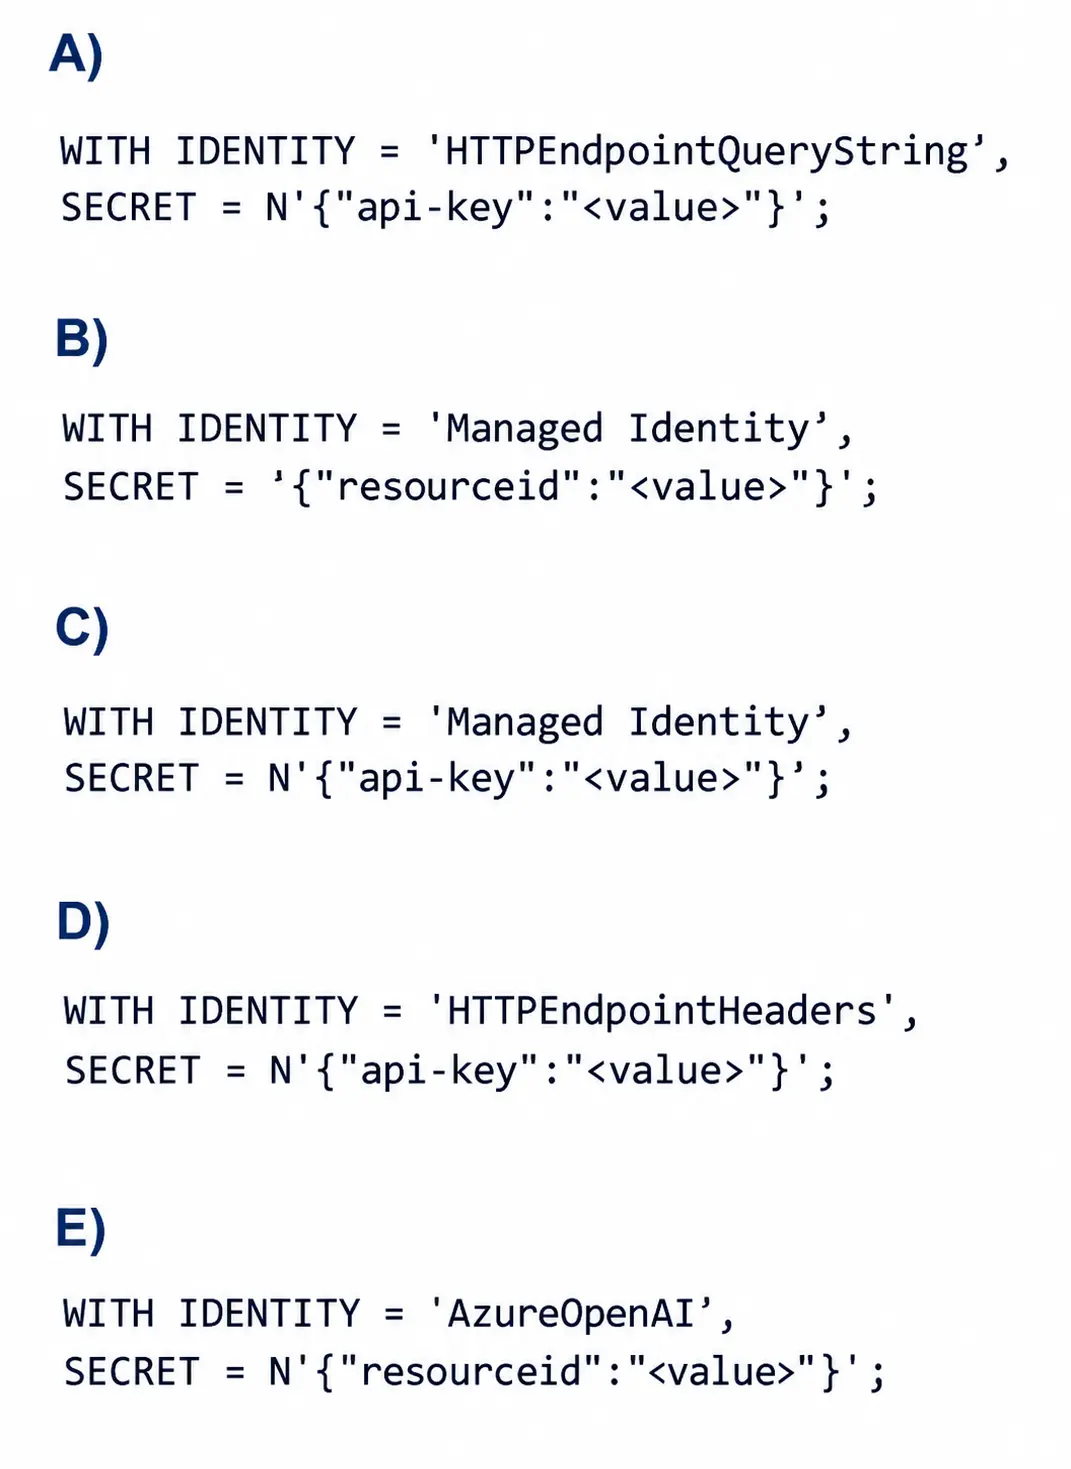
What should you insert at line 02?
-
Option A:Correct
Option A
-
Option B:Correct
Option B
-
Option C:Correct
Option C
-
Option D:Correct
Option D
-
Option E:Correct
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: B
Explanation
The correct answer is Option B because the requirement is to call an Azure OpenAI REST endpoint from SQL Server 2025 while providing the highest level of security , and the instance already has a managed identity enabled . For Microsoft’s SQL AI features, the preferred secure pattern is to use a database scoped credential with IDENTITY = ' Managed Identity ' instead of storing an API key. Microsoft documents that SQL Server 2025 supports managed identity for external AI endpoints, and for Azure OpenAI the credential secret uses the Cognitive Services resource identifier: { " resourceid " : " https://cognitiveservices.azure.com " } .
So line 02 should be:
WITH IDENTITY = ' Managed Identity ' ,
SECRET = ' { " resourceid " : " https://cognitiveservices.azure.com " } ' ;
Why the other options are incorrect:
A and D use HTTP header or query-string credentials with an API key , which is less secure than managed identity because a secret key must be stored and rotated manually. Microsoft recommends managed identity where supported to avoid embedded secrets.
C mixes Managed Identity with an api-key secret, which is not the correct pattern for Azure OpenAI managed-identity authentication.
E uses an invalid identity value for this scenario. The accepted credential identities for external REST endpoint calls include HTTPEndpointHeaders , HTTPEndpointQueryString , Managed Identity , and Shared Access Signature .
Because the endpoint is Azure OpenAI and the question explicitly asks for the highest security , managed identity with the Cognitive Services resource ID is the Microsoft-aligned answer.
-
-
Question 2
Single answerYou need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
-
Option A:Correct
a computed column that manually compares vector values
-
Option B:Correct
a standard nonclustered index on the Fmbeddings (vector (1536)) column
-
Option C:Correct
a full-text index on the Fmbeddings (vector (1536)) column
-
Option D:Correct
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: D
Explanation
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector(1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
A would require manual comparison logic and would increase latency rather than minimize it.
B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft’s current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam-aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
-
-
Question 3
Multiple answersYou need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
-
Option A:Correct
Enable snapshot isolation on the database.
-
Option B:Correct
Use a trigger to automatically rewrite malformed JSON.
-
Option C:Correct
Add foreign key constraints on the table.
-
Option D:Correct
Create a unique index on a hash of the payload.
-
Option E:Correct
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: D, E
Explanation
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft’s JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design. Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam-consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
-