
Exam Overview
| Exam Code | DP-700 |
| Exam Name | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Vendor | Microsoft |
| Total Questions | 113 |
| Last Updated | 26-Oct, 2026 |
Why CertsPoint?
- Latest & Verified Questions
- Detailed Explanations
- Regular Updates
- Full-Length Practice Tests
- Boost Your Exam Confidence
PDF Study Materials
Downloadable guides and resources
Practice Tests
Full-length tests with real exam experience
Progress Tracking
Monitor your performance and improvement
Study Anywhere
Access on desktop, tablet, and mobile
Secure Payment
Privacy Protected
Money Back Guarantee
Free DP-700 Practice Questions
Explore 12 free practice questions for the Microsoft DP-700 exam and review the answers and explanations to support your preparation.
-
Question 1
Multiple answersYou need to populate the MAR1 data in the bronze layer.
Which two types of activities should you include in the pipeline? Each correct answer presents part
of the solution-
Option A:Correct
ForEach
-
Option B:Correct
Copy data
-
Option C:Correct
WebHook
-
Option D:Correct
Stored procedure
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: A, B
Explanation
MAR1 has seven entities, each accessible via a different API endpoint. A ForEach activity is required
to iterate over these endpoints to fetch data from each one. It enables dynamic execution of API calls
for each entity.
The Copy data activity is the primary mechanism to extract data from REST APIs and load it into the
bronze layer in Delta -
-
Question 2
Single answerYou need to ensure that usage of the data in the Amazon S3 bucket meets the technical
requirements.
What should you do?-
Option A:Correct
Create a workspace identity and enable high concurrency for the notebooks.
-
Option B:Correct
Create a shortcut and ensure that caching is disabled for the workspace.
-
Option C:Correct
Create a workspace identity and use the identity in a data pipeline.
-
Option D:Correct
Create a shortcut and ensure that caching is enabled for the workspace.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: B
Explanation
To ensure that the usage of the data in the Amazon S3 bucket meets the technical requirements, we
must address two key points:
Minimize egress costs associated with cross-cloud data access: Using a shortcut ensures that Fabric
does not replicate the data from the S3 bucket into the lakehouse but rather provides direct access to
the data in its original location. This minimizes cross-cloud data transfer and avoids additional egress
costs.
Prevent saving a copy of the raw data in the lakehouses: Disabling caching ensures that the raw data
is not copied or persisted in the Fabric workspace. The data is accessed on-demand directly from the
Amazon S3 bucket. -
-
Question 3
Drag & DropHOTSPOT
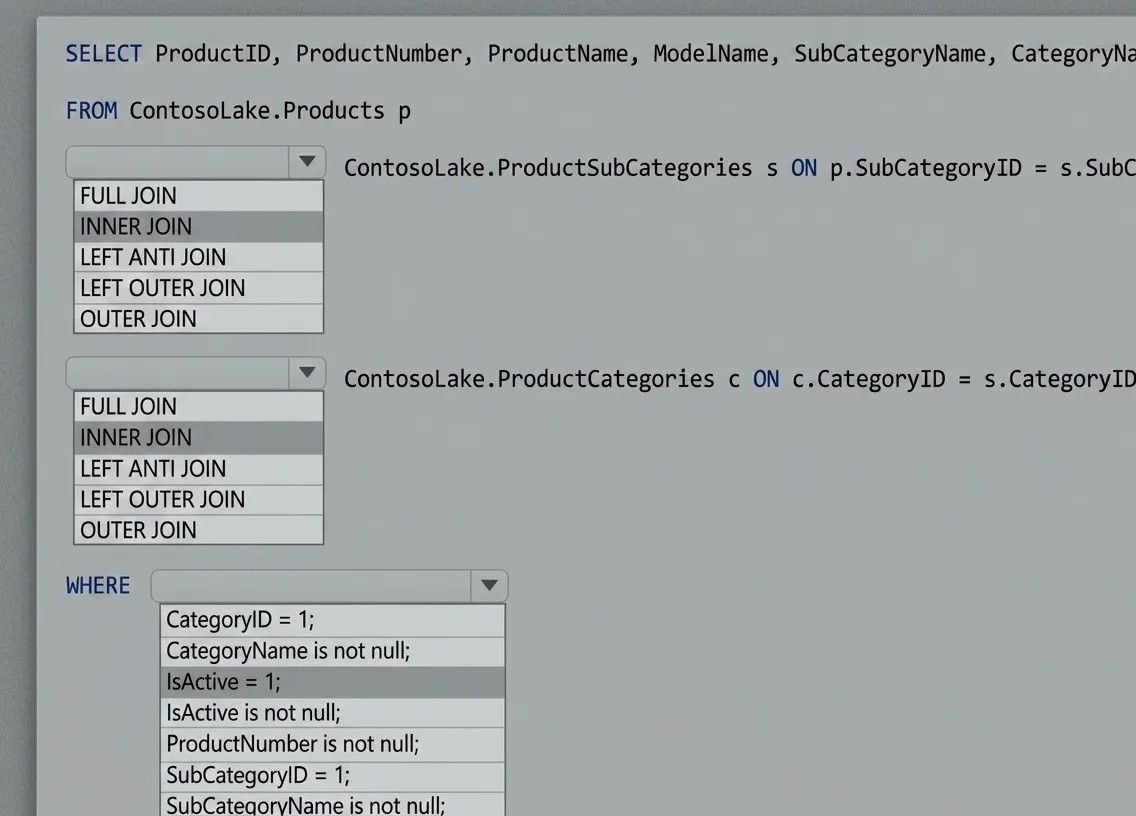
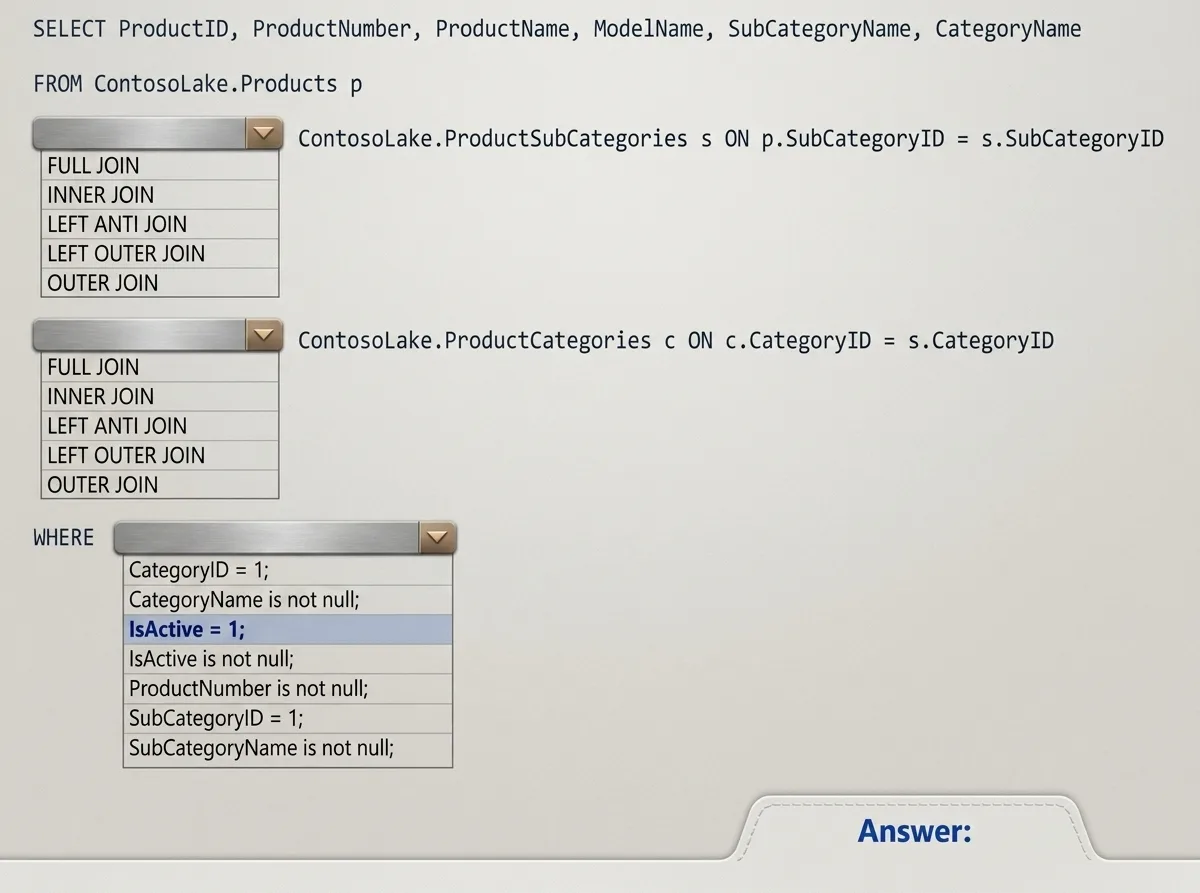
You need to create the product dimension.
How should you complete the Apache Spark SQL code? To answer, select the appropriate options in
the answer area.
NOTE: Each correct selection is worth one point.Show Answer & Explanation Hide Answer & Explanation
Correct Answer
Explanation
A screenshot of a computer Description automatically generated
Join between Products and ProductSubCategories:
Use an INNER JOIN.
The goal is to include only products that are assigned to a subcategory. An INNER JOIN ensures that
only matching records (i.e., products with a valid subcategory) are included.
Join between ProductSubCategories and ProductCategories:
Use an INNER JOIN.
Similar to the above logic, we want to include only subcategories assigned to a valid product
category. An INNER JOIN ensures this condition is met.
WHERE Clause
Condition: IsActive = 1
Only active products (where IsActive equals 1) should be included in the gold layer. This filters out
inactive products. -
Question 4
Single answerYou need to ensure that the data analysts can access the gold layer lakehouse.
What should you do?-
Option A:Correct
Add the DataAnalyst group to the Viewer role for WorkspaceA.
-
Option B:Correct
Share the lakehouse with the DataAnalysts group and grant the Build reports on the default
semantic model permission. -
Option C:Correct
Share the lakehouse with the DataAnalysts group and grant the Read all SQL Endpoint data
permission. -
Option D:Correct
Share the lakehouse with the DataAnalysts group and grant the Read all Apache Spark permission
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: C
Explanation
Data Analysts' Access Requirements must only have read access to the Delta tables in the gold layer
and not have access to the bronze and silver layers.
The gold layer data is typically queried via SQL Endpoints. Granting the Read all SQL Endpoint data
permission allows data analysts to query the data using familiar SQL-based tools while restricting
access to the underlying files. -
-
Question 5
Drag & DropHOTSPOT
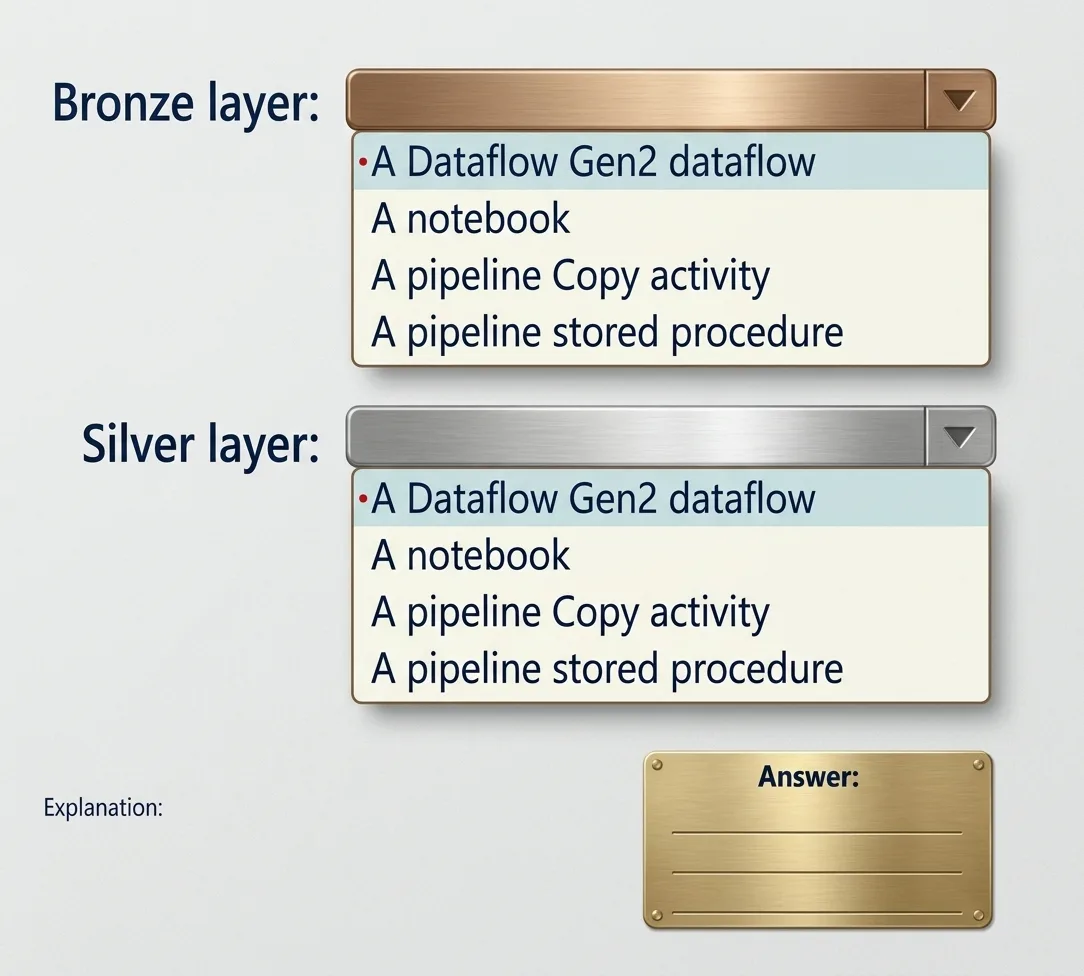
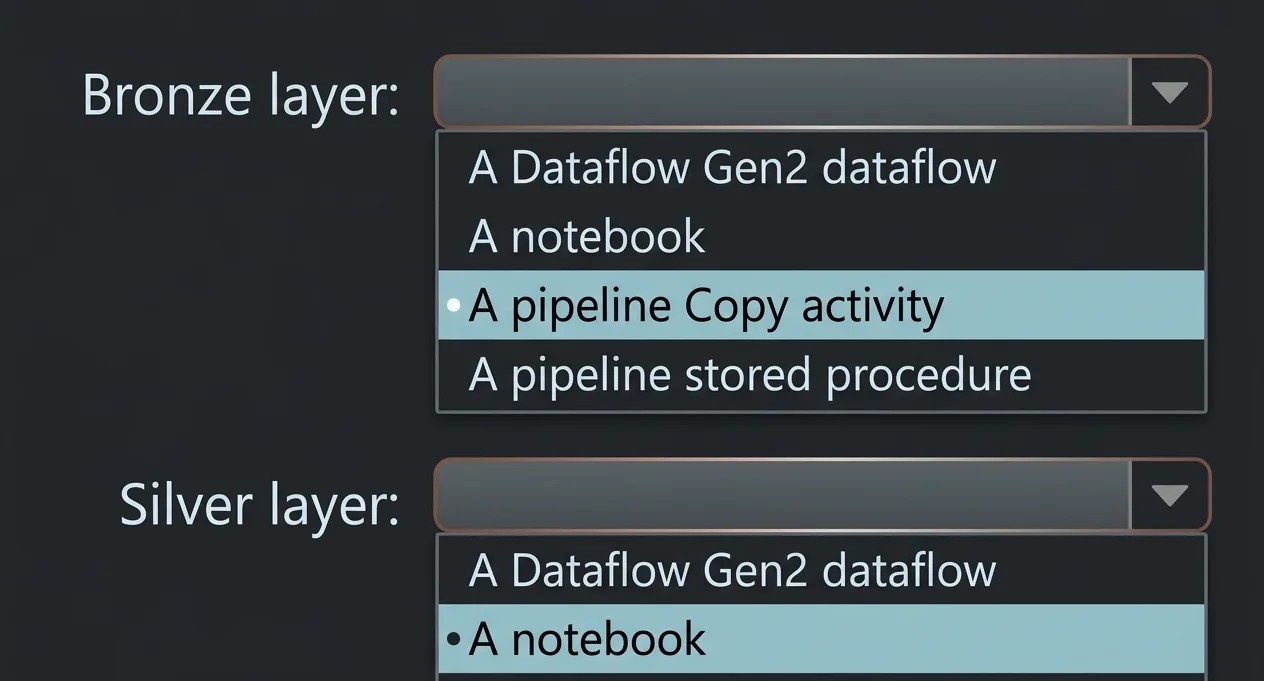
You need to recommend a method to populate the POS1 data to the lakehouse medallion layers.
What should you recommend for each layer? To answer, select the appropriate options in the answer
area.
NOTE: Each correct selection is worth one point.Show Answer & Explanation Hide Answer & Explanation
Correct Answer
Explanation
A screenshot of a computer Description automatically generated
Bronze Layer: A pipeline Copy activity
The bronze layer is used to store raw, unprocessed data. The requirements specify that no
transformations should be applied before landing the data in this layer. Using a pipeline Copy activity
ensures minimal development effort, built-in connectors, and the ability to ingest the data directly
into the Delta format in the bronze layer.
Silver Layer: A notebook
The silver layer involves extensive data cleansing (deduplication, handling missing values, and
standardizing capitalization). A notebook provides the flexibility to implement complex
transformations and is well-suited for this task. -
Question 6
Drag & DropHOTSPOT You need to meet the development requirements for the FeedbackJson column
How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer
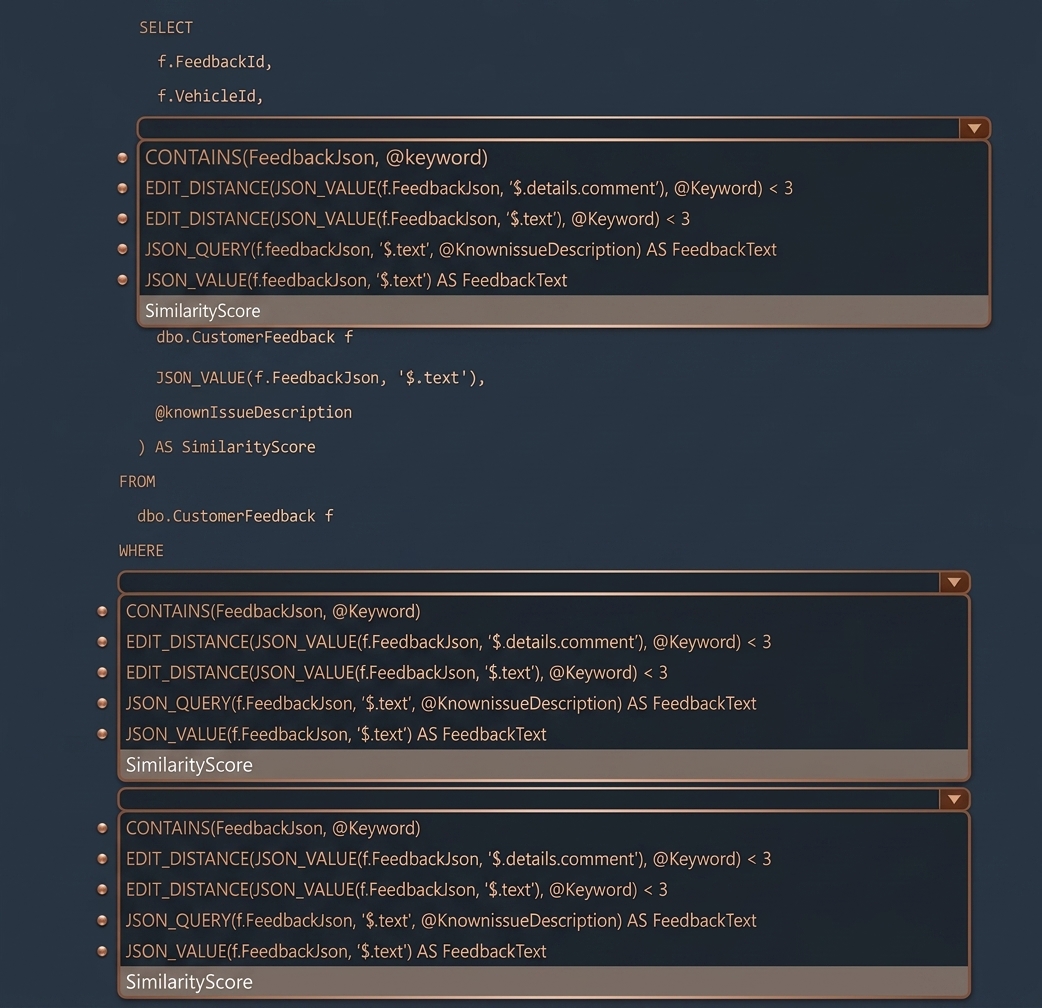
Explanation
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column. First, to extract the customer feedback text from the JSON document, the correct expression is JSON_VALUE(f.FeedbackJson, '$.text') AS FeedbackText. Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array. Since $.text is the textual feedback string, JSON_VALUE is the correct function. Second, to filter rows where the JSON text contains a keyword, the best choice is CONTAINS(FeedbackJson, @Keyword). The scenario explicitly states that FeedbackJson already has a full-text index, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering. Third, to order the results by similarity score, highest first, the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query. JSON_VALUE(f.FeedbackJson, '$.text') AS FeedbackText CONTAINS(FeedbackJson, @Keyword) SimilarityScore
-
Question 7
Multiple answersYou need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
-
Option A:Correct
Enable snapshot isolation on the database.
-
Option B:Correct
Use a trigger to automatically rewrite malformed JSON.
-
Option C:Correct
Add foreign key constraints on the table.
-
Option D:Correct
Create a unique index on a hash of the payload..
-
Option E:Correct
Add a check constraint that validates the JSON structure.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: D, E
Explanation
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads, and these two controls address those two problems directly. Microsoft’s JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON, and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted. For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design. Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index. That makes a persisted hash-based computed column plus a unique index a practical and exam-consistent way to reject duplicate payloads efficiently. The other options do not solve the stated root causes: Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection. A trigger to rewrite malformed JSON is not the right integrity control and is brittle. Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
-
-
Question 8
Single answerYou need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
-
Option A:Correct
Export the database schema as a .dacpac file and load the schema into a GitHub Copilot context window.
-
Option B:Correct
Add the schema to a GitHub Copilot instruction file.
-
Option C:Correct
Use an MCP server D. Include the database project in the code repository.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: C
Explanation
The best recommendation is to use an MCP server. In the official DP-800 study guide, Microsoft explicitly lists skills such as configuring Model Context Protocol (MCP) tool options in a GitHub Copilot session and connecting to MCP server endpoints, including Microsoft SQL Server and Fabric Lakehouse. That makes MCP the exam-aligned mechanism for enabling AI-assisted tools to work with live database context rather than static snapshots. This also matches the stated development requirement: the team will use Visual Studio Code and GitHub Copilot and needs to retrieve live metadata from the databases. Microsoft’s documentation for GitHub Copilot with the MSSQL extension explains that Copilot works with an active database connection, provides schema-aware suggestions, supports chatting with a connected database, and adapts responses based on the current database context. Microsoft also documents MCP as the standard way for AI tools to connect to external systems and data sources through discoverable tools and endpoints. The other options do not satisfy the “live metadata” requirement as well: A .dacpac is a point-in-time schema artifact, not live metadata. A Copilot instruction file provides guidance, not live database discovery. Including the database project in the repository helps source control and deployment, but it still does not provide live database metadata by itself.
-
-
Question 9
Single answerYou need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
-
Option A:Correct
vehicleLocation
-
Option B:Correct
incidentDescrlption
-
Option C:Correct
incidentType
-
Option D:Correct
SeverityScore
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: B
Explanation
The correct column to use for generating embeddings is incidentDescrlption because embeddings are intended to represent the semantic meaning of rich textual content, not simple categorical, numeric, or location-only values. Microsoft’s DP-800 study guide explicitly includes skills such as identifying which columns to include in embeddings, generating embeddings, and implementing semantic vector search for scenarios where users need to find similar records based on meaning rather than exact matches. In this scenario, analysts report that it is difficult to find similar incidents based on details such as weather, traffic conditions, and location. Those are descriptive context elements that are typically captured in a free-text incident description field. An embedding generated from incidentDescrlption can encode the semantic relationships among these narrative details, making it suitable for similarity search, semantic search, and RAG retrieval. Microsoft documentation on vectors and embeddings explains that embeddings are generated from text data and then stored for vector search to find semantically related items. The other options are weaker choices: vehicleLocation is too narrow and usually better handled with geospatial filtering, not embeddings. incidentType is likely categorical and too low in semantic richness. SeverityScore is numeric and not appropriate as the primary source for semantic embeddings. Microsoft also notes that when multiple useful attributes exist, you can either embed each text column separately or concatenate relevant text fields into one textual representation before generating the embedding. But among the options given, the best and most exam-aligned answer is the textual narrative column: incidentDescrlption.
-
-
Question 10
Multiple answersYou need to configure models for the project.
What are two possible ways to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.-
Option A:Correct
Overlay the existing FinanceExt model and populate the solution definition.
-
Option B:Correct
Modify the DefaultModelForNewProject setting in the DefaultConfig.xml file and name the model
FinanceExt. -
Option C:Correct
Create a new model that extends the existing FinanceExt model.
-
Option D:Correct
Extend the existing FinanceExt model and populate the project model definition.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: A, D
Explanation
When working with Microsoft Dynamics 365 Finance and Operations, you should never modify an existing model directly. Instead, customization is done through extensions.
✅ A. Overlay the existing FinanceExt model and populate the solution definition.
This is a valid way to configure the project model by using the existing model and defining it in the solution. Historically, overlaying was used to modify existing application objects.
❌ B. Modify the DefaultModelForNewProject setting in the DefaultConfig.xml file and name the model FinanceExt.
This only changes the default model name for new projects. It does not configure or extend the model required for the project.
❌ C. Create a new model that extends the existing FinanceExt model.
Models do not extend other models directly. Instead, a model can reference another model. Therefore, this statement is not correct.
✅ D. Extend the existing FinanceExt model and populate the project model definition.
This is the recommended approach. You create extensions and configure the project so that it uses the existing FinanceExt model. -
-
Question 11
Single answerYou need to update the CashDisc report to meet the requirements.
-
Option A:Correct
Customize the existing CashDisc report in the overlayering model and add the new field to the
design. -
Option B:Correct
Extend the existing CashDisc report in the extension model and add the new field to the design.
-
Option C:Correct
Duplicate the existing CashDisc report in the extension model and add the new field to the design.
-
Option D:Correct
Delete the existing CashDisc report in the extension model and create a new report.
Show Answer & Explanation Hide Answer & Explanation
Correct Answer: B
Explanation
✅ B. Add a post handler to the method that checks the enumeration and logic for your new enumeration values using the enumeration value.
Why?
In Dynamics 365 Finance and Operations, the recommended approach is to use extensions and event handlers rather than modifying existing application code.- A post handler allows you to extend the behavior of an existing method without changing the original code.
- This follows the extension model and keeps your customization upgrade-safe.
-
You can add logic for the new enum values (
Quarantine,InTransit) in the handler.
❌ A. Add a new case statement in the model of the existing code.
This requires modifying the original method and adding new code directly to the existing application object, which is essentially overlayering. Overlayering is not the recommended approach and should be avoided whenever an extension mechanism is available. -
-
Question 12
Drag & DropHOTSPOT
You need to modify the CashDisc form to meet the requirements.
Which objects should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.Show Answer & Explanation Hide Answer & Explanation
Correct Answer
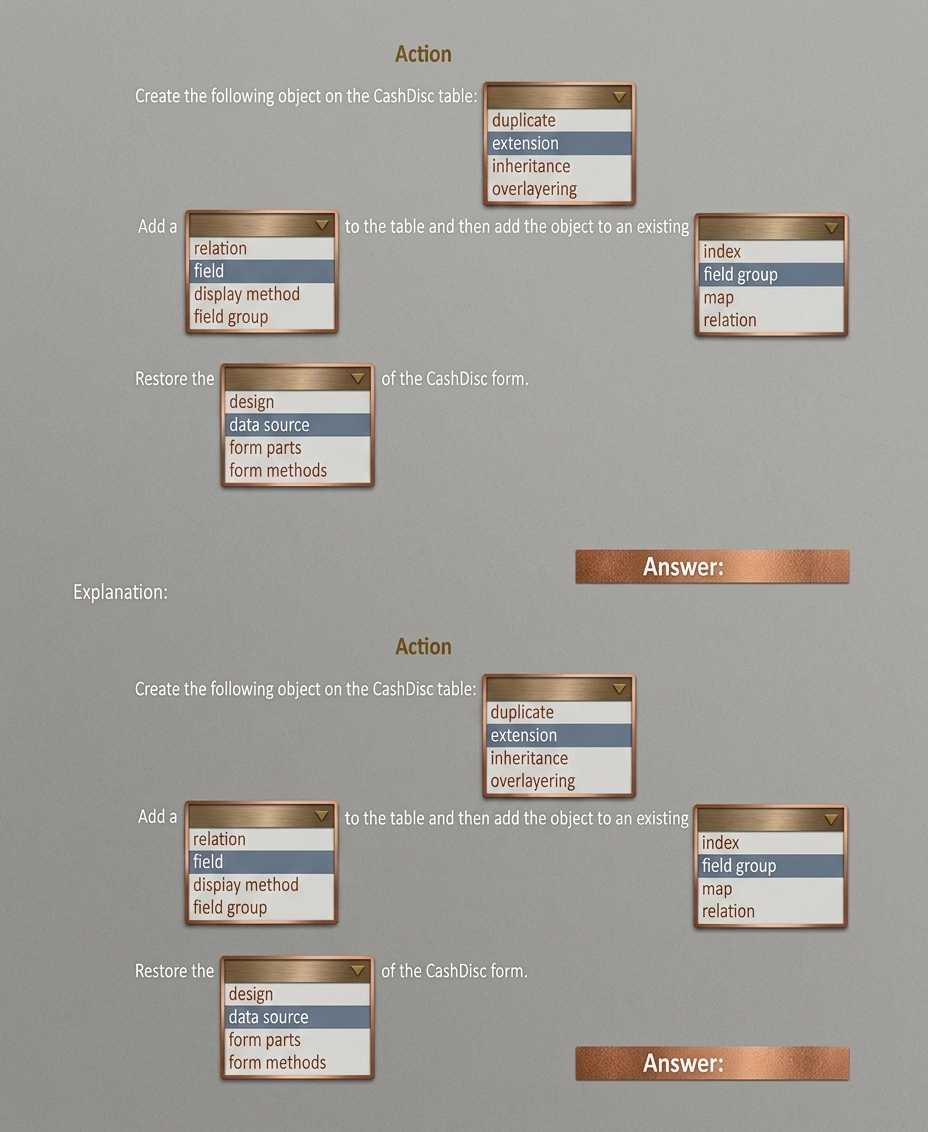
Explanation
Scenario: CashDisc form
Box 1: extension
To add a new field to an existing table, you must first create a table extension.
You can add new data sources to existing forms through extension. Follow these steps.
In the extension model, create a form extension for the selected form.
Right-click the form extension, and then select New Data Source.
Box 4: data source
Often, the information that is stored in existing tables doesn't satisfy customer requirements.
Therefore, additional tables must be created, and data from those tables must be shown on pages.
You must extend the CashDisc form to add a new field named MinimumInvoiceAmount to the form.
You must add a new Extended Data Type to the extension model for the new field. The new field
must be added above the discount method field. The field must display 10 characters.